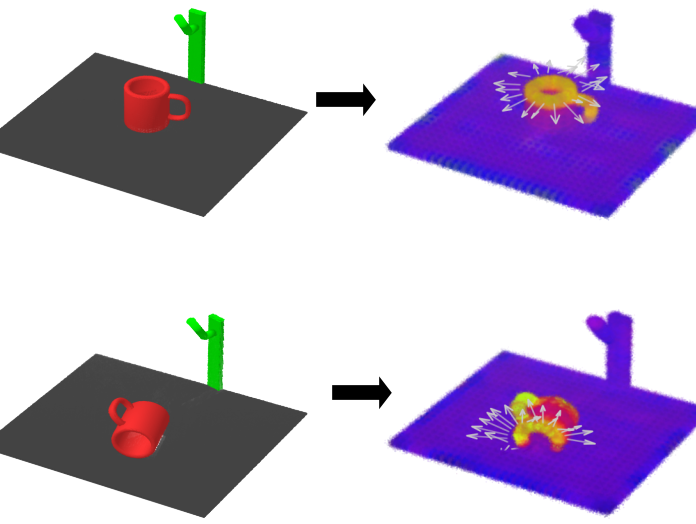
Mirror: Self-Improving Video-to-Action Models
Paper and code coming soon
I work on video generative models for embodied intelligence and computer use agents.
PhD student at MIT CSAIL, in the Scene Representation Group
I'm a PhD student in the Scene Representation Group at MIT CSAIL, working with Vincent Sitzmann. I work on video generative models for embodied intelligence and computer use agents. I'm interested in how video models can help agents plan actions and learn through interaction.
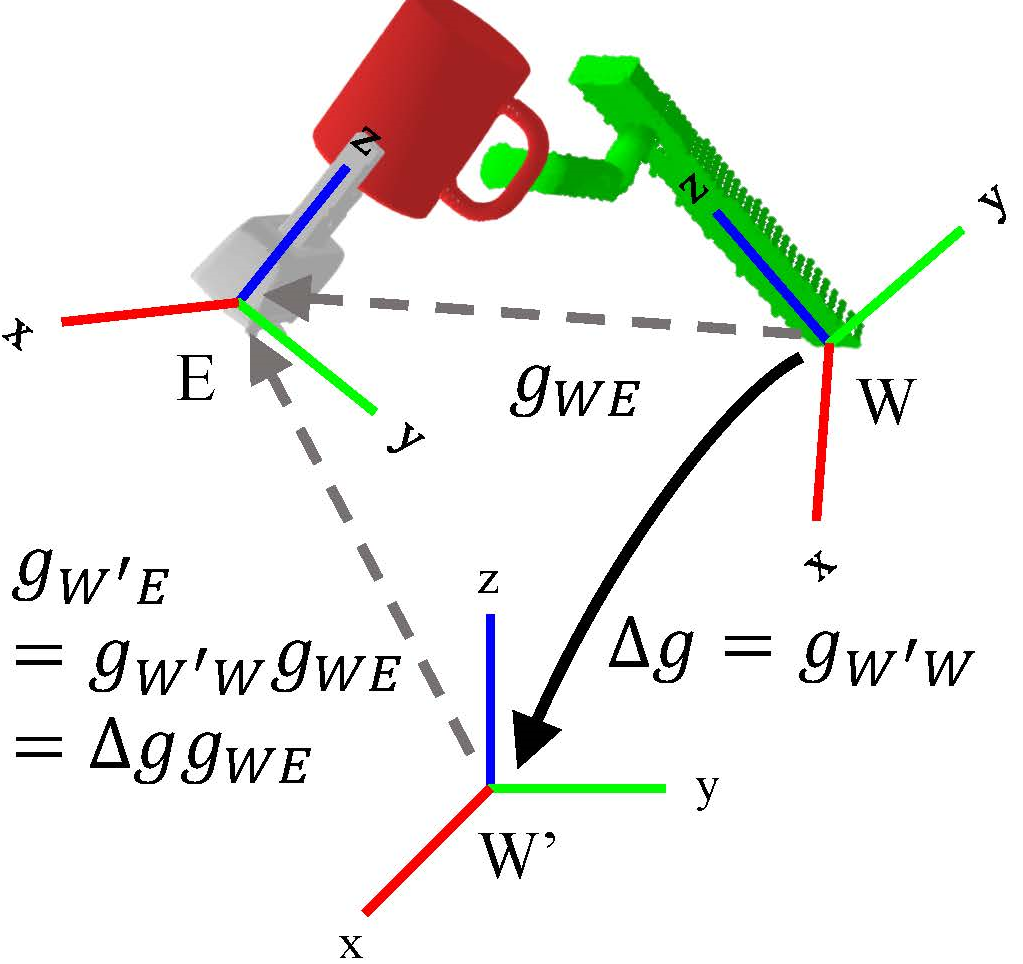
Previously, I worked on geometric representations and equivariant generative models for robotic manipulation. I received my master's in Artificial Intelligence and bachelor's in Mechanical Engineering from Yonsei University, where I was advised by Jongeun Choi.
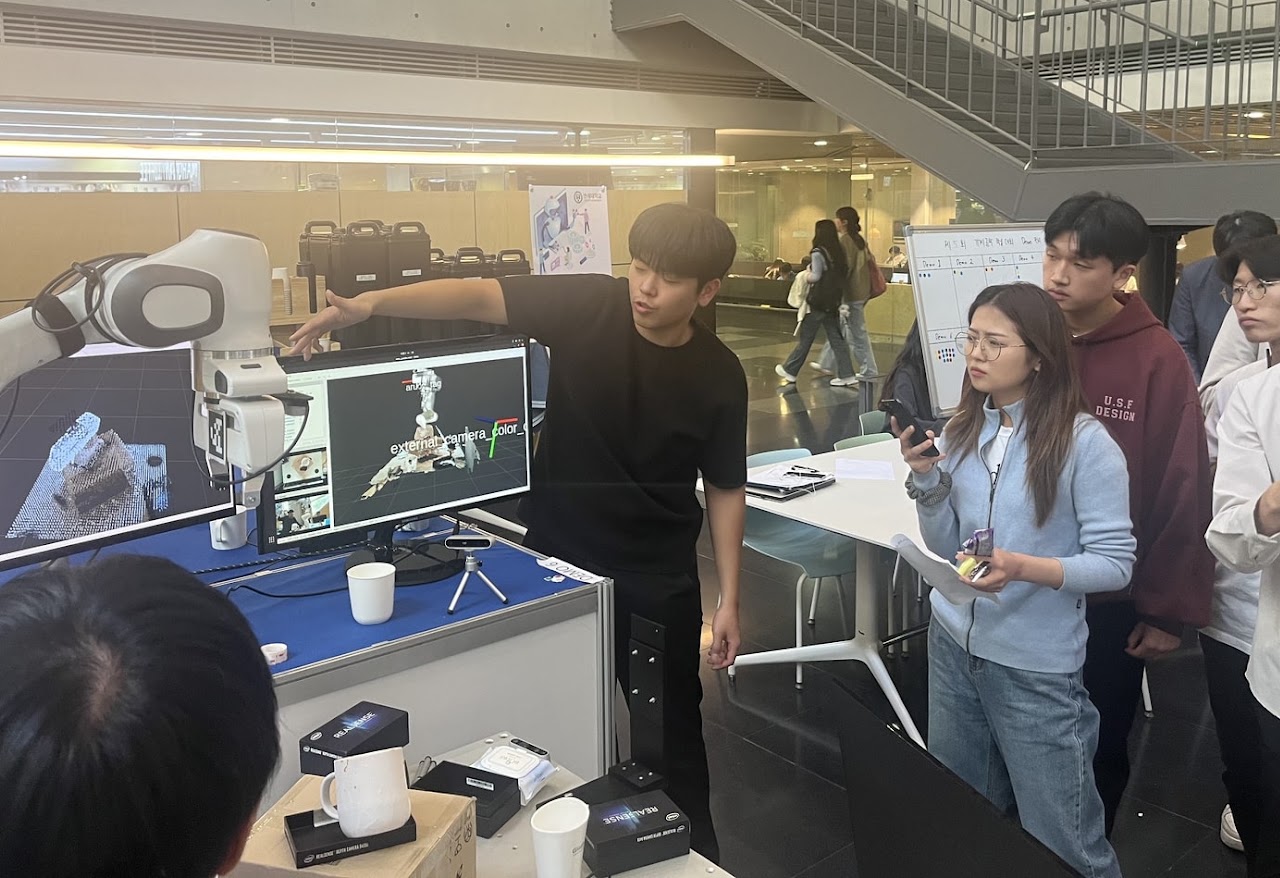
Diffusion-EDFs technical demonstration at Yonsei's Mechanical Engineering Graduate Student Academic Conference.
Best Technical Demonstration Award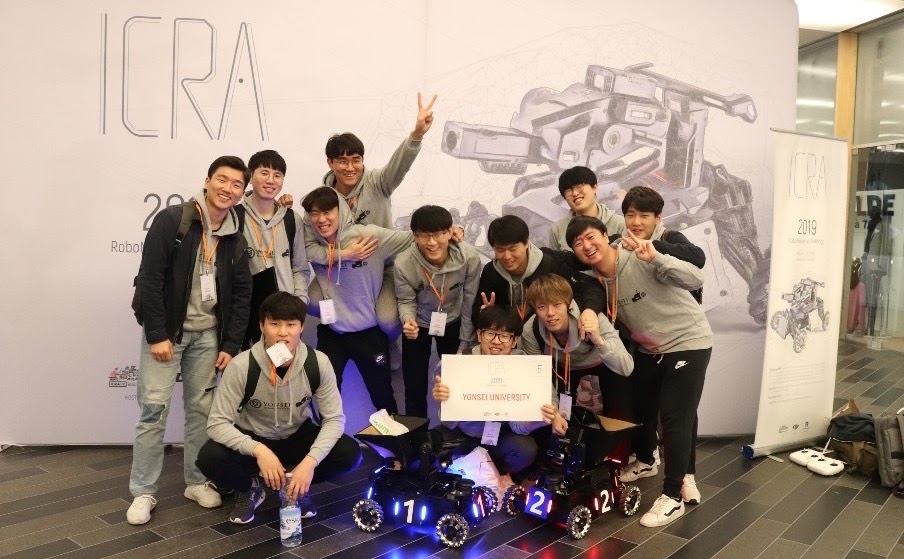
ROS, SLAM, navigation, motion planning, and sim-to-real. Montréal, Canada.
3rd Prize · Top 4 of 68 technical reportsScaling View Synthesis Transformers at CVPR 2026.
XFactor selected for an Oral presentation at ICLR 2026.
Started my PhD at MIT CSAIL, with Vincent Sitzmann and the Scene Representation Group.
Diffusion-EDFs selected as a CVPR 2024 Highlight.
Joining MIT EECS for a PhD, beginning Fall 2024.
Diffusion-EDFs accepted to CVPR 2024.
Denoising Heat-inspired Diffusion accepted to the NeurIPS Workshop on Diffusion Models.
Best Technical Demonstration Award for Diffusion-EDFs at Yonsei University.
Diffusion-EDFs preprint released.
Best Paper Award at the RSS Workshop on Symmetries in Robot Learning.
Equivariant Descriptor Fields workshop paper accepted as an oral at RSS. Watch the presentation
Equivariant Descriptor Fields accepted to ICLR 2023.
Questions about my research, or ideas to work on together? Send me an email.